
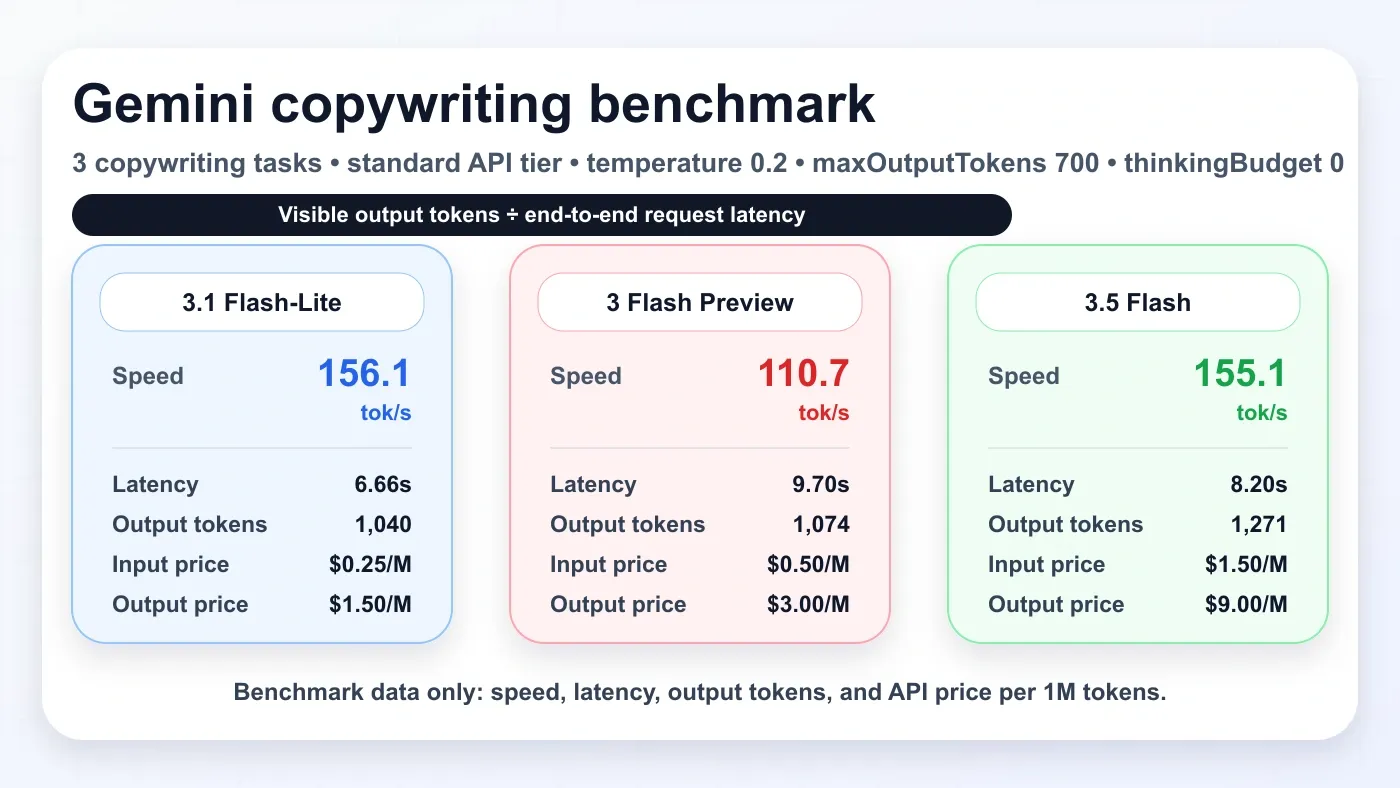
This is a short benchmark note. I tested three Gemini models with three copywriting tasks and recorded only the simple numbers: output tokens, total latency, visible output tokens per second, and API price.
The low-cost model tested here is Gemini 3.1 Flash-Lite with model ID gemini-3.1-flash-lite. The middle model is Gemini 3 Flash Preview with model ID gemini-3-flash-preview. The newest model at test time was Gemini 3.5 Flash with model ID gemini-3.5-flash.
October 12, 2026 update: Google deprecated Gemini 3.5 Flash on October 8, 2026. Requests to gemini-3.5-flash now go to Gemini 3.6 Flash automatically. 3.6 and 3.8 Flash cost $0.75 input / $3.75 output per 1M tokens until December 31, 2026 ($1.50 / $7.50 after). Gemini 3.1 Flash-Lite can shut down as early as May 7, 2027; Google recommends Gemini 3.5 Flash-Lite ($0.30 / $2.50) as its replacement. For current speed, see the live numbers below; the May benchmark was not rerun. See the current Gemini model ranking and prices.
Live speed in October 2026
OpenRouter publishes median (P50) latency and throughput from real API traffic. These are its Google AI Studio numbers, read on October 8, 2026. Latency is the time until the response starts; throughput is output tokens per second while it streams. They mix all prompt types and reasoning settings, so compare the models with each other here, not with the controlled May test below.
| Model | Price (input / output per 1M) | Latency (P50) | Throughput (P50) |
|---|---|---|---|
gemini-3.8-flash | $0.75 / $3.75 | 2.61s | 78 tok/s |
gemini-3.5-flash | Deprecated; routes to 3.6 Flash | 1.79s | 169 tok/s |
gemini-3-flash-preview | $0.50 / $3.00 | 1.30s | 82 tok/s |
gemini-3.5-flash-lite | $0.30 / $2.50 | 0.74s | 114 tok/s |
gemini-3.1-flash-lite | $0.25 / $1.50 | 0.67s | 134 tok/s |
In live traffic, 3.8 Flash is the slowest of the five, probably because more of its requests use reasoning. 3.5 Flash streamed fastest on October 8, but its requests now go to 3.6 Flash. When speed matters more than quality, the Flash-Lite models start responding in under a second at the lowest prices.
Benchmark setup
| Setting | Value |
|---|---|
| Models | gemini-3.1-flash-lite, gemini-3-flash-preview, gemini-3.5-flash |
| Tasks | 3 copywriting tasks |
| API tier | Gemini Developer API standard tier |
| Generation config | temperature: 0.2, maxOutputTokens: 700, thinkingBudget: 0 |
| Speed metric | Visible output tokens ÷ end-to-end request latency |
| Run date | May 19, 2026 |
Speed results

| Model | Total output tokens | Total latency | Weighted speed | Average latency |
|---|---|---|---|---|
gemini-3.1-flash-lite | 1,040 | 6.66s | 156.1 tok/s | 2.22s |
gemini-3-flash-preview | 1,074 | 9.70s | 110.7 tok/s | 3.23s |
gemini-3.5-flash | 1,271 | 8.20s | 155.1 tok/s | 2.73s |
API price

| Model | Input price | Output price |
|---|---|---|
gemini-3.1-flash-lite (shutdown earliest May 7, 2027) | $0.25 / 1M text, image, or video tokens | $1.50 / 1M output tokens |
gemini-3-flash-preview | $0.50 / 1M text, image, or video tokens | $3.00 / 1M output tokens |
gemini-3.5-flash (deprecated Oct 8, 2026; routes to 3.6 Flash) | $1.50 / 1M input tokens | $9.00 / 1M output tokens |
Speed vs output price

Raw data summary
- Fastest in this run: Gemini 3.1 Flash-Lite at 156.1 tok/s.
- Very close second: Gemini 3.5 Flash at 155.1 tok/s.
- Slowest in this run: Gemini 3 Flash Preview at 110.7 tok/s.
- Lowest output price: Gemini 3.1 Flash-Lite at $1.50 / 1M output tokens.
- Highest output price: Gemini 3.5 Flash at $9.00 / 1M output tokens.
Sources
- Google announcement: Gemini 3.5
- Gemini Developer API pricing
- Gemini API models
- OpenRouter model pages (live latency and throughput by provider)